Ephemora-cell
Ephemora-cell is an ephemeral, stateless, capability-bound execution boundary for untrusted AI and agent-generated code.
create → constrain → execute → prove → destroy
Every execution starts from a clean state, runs under limits the host granted — fuel,
memory, time, I/O, output size, filesystem and network capability — can produce signed
evidence of what happened, and ends without carrying execution state into the next run.
The evidence persists. The execution state does not.
Built for AI agents, MCP tools, plugins, code interpreters, and other untrusted workloads.
AI Agent / Application
        │
        ▼
   Tool / Plugin / MCP
        │
        ▼
 ┌───────────────────────┐
 │     Ephemora-cell     │
 │                       │
 │ Capabilities          │
 │ Resource budgets      │
 │ WASI sandbox          │
 │ Execution record      │
 └──────────┬────────────┘
            ▼
       WASM module
~0.5 ms warm · ~3M executions/hour per core (one-liner) up to ~5.5M pooled · deterministic, not "isolated and hoped for"





Quick Start ·
Security ·
MCP ·
GitHub Action ·
Benchmarks ·
Docs
Status (2026-10-05): published on PyPI: 1.1.0 (2026-10-05, released as the signed tag v1.1.0 — changelog) · previous release 1.0.5 (2026-09-29, licensing & security-readiness) · 1.1.0: bring-your-own-interpreter release — the module cap is a knob, the P1 #12 sync blockade moved to the call layer, egress grants are enforced AND authenticated against a trust root kept outside the grants directory, and per-call receipts are bound to one execution (changelog) · license now BUSL-1.1 (source-available; ≤ 1.0.4.3 stays Apache-2.0 — ADR-010) · 2026-09-24 wasmtime advisory wave triaged with measured evidence (see SECURITY.md) · latest reproducible evidence: 2026-10-02 (interpreter-guest measurement, benchmarks/results/) · 957 tests passing, 90% coverage (see CI badge — refreshed per release)
What is Ephemora-cell?
Ephemora-cell is an embeddable execution boundary for running untrusted, often AI-generated code: WASM/WASI isolation, explicit capability control, enforced CPU/fuel, memory, I/O and time limits, bounded output, and structured — optionally signed — execution records. Runtime + security boundary + accounting in one pip install. It uses Wasmtime to implement that boundary — WASM is the mechanism, the controlled execution of untrusted code is the product.
What the 1.1 boundary actually enforces, each of it behind a named test (see
SECURITY.md for the claims and their limits):
- Capability, not convention. A run sees only what it was granted: preopens are
revalidated at grant time, the guest never gets sockets, and the host does not
follow a file name the guest could have created (
O_NOFOLLOW + regular-file check
- atomic publication on every shared path).
- Authenticated grants with real limits. Egress is host-mediated after the run.
Each tool's grant must be a DSSE envelope signed by a key in an operator trust root
kept outside the grants directory, and its window, call cap and revocation are
enforced against an append-only ledger — intersected with the operator's own
allowlist, per request and per redirect hop, with the tighter resource cap
winning.
--egress-grants-required removes the allowlist fallback entirely.
- Resolved addresses pinned. A name that answers with loopback, RFC1918, CGNAT,
link-local or metadata space is refused at resolve time, and the vetted address is
the address connected to — no rebinding window between the two.
- Signed, one-of-one evidence. Receipts sign the exact canonical bytes shown to the
caller and carry a fresh
report_id plus issue time, so a receipt is evidence about
one execution; the verifier, outside Cell, decides whether it has been seen before.
- Fail-closed as a default posture. A broken grant set, an unreadable ledger, an
empty authority directory or a malformed request artifact produces a refusal with an
audit line, not a silent pass — and refuses at startup where startup is the safe
moment.
- Nothing carried between runs. No sandbox directory, no engine reuse of a
previous run's state, no inherited authority — measured over thousands of
consecutive runs (
benchmarks/statelessness_probe.py).
Why Ephemora-cell?
Wasmtime gives you a WASM runtime.
Ephemora-cell builds an application-level execution boundary around it:
Wasmtime:            Ephemora-cell:
    Execute WASM         Execute WASM
                         + define capabilities
                         + enforce budgets (fuel, memory, time, I/O)
                         + bound output
                         + collect execution metadata
                         + produce execution records (sign-ready)
                         + integrate with agents and MCP
Why Cell for agent execution?
Ephemora-cell is not trying to replace general-purpose containers or full development VMs. It targets a narrower execution path: high-frequency, untrusted agent and MCP workloads that benefit from a small capability surface, explicit resource accounting, and sub-millisecond warm sandbox execution. For agent infrastructure, this means Cell can act as a lightweight execution backend beneath an existing harness rather than requiring a new agent framework. The intended trade-off is explicit: less generality than a full Linux sandbox, in exchange for a smaller execution surface, tighter capability control, and lower per-call overhead.
The problem this answers: AI agents increasingly need to write and execute code, call tools, and run plugins. The question that decides whether that is safe: how do you let an agent execute untrusted code without giving that code access to your host, your credentials, your network, or unlimited compute — with nothing pre-opened by default? Raw runtimes leave that boundary to you. Cell is that boundary.
Agent-generated code is different from application code: it can be buggy, computationally unbounded, unexpectedly expensive — or hostile. The runtime must enforce boundaries, not document them. Every Cell run does:
- Enforced, not promised — fuel metering (CPU), memory caps, epoch-based wall-clock timeouts, output caps and I/O budgets run per execution; the guest cannot reach any of them off, and the two settings an operator can widen — the module size cap and the WASI sync opt-out — are named in the execution record so a widened run never reads as a default one (RFC 8785 JCS, sign-ready).
- Deterministic loop-stop — a hostile or buggy module that loops forever is stopped at exactly the budget you set, every time; the run cannot overshoot its fuel budget. The epoch-based wall-clock timeout is the safety net on top — fuel counts CPU, the clock bounds everything else.
- Measured isolation advantage — of the attack vectors that succeed against a stock Docker container (shell, fork, socket, host filesystem, symlink escape, …), all 8 are blocked here (live-verified, script in the repo).
- Sub-millisecond warm execution — 0.17 ms guest / 0.51 ms end-to-end (pooled, measured 2026-09-14;
benchmarks/results/).
Why now — 2026 evidence that detection and containers are not enough (literature — measured:false for Cell; the measured rows live in the evidence ladder and never mix with these). SABER — the SandboxEscapeBench program (UK AI Security Institute & Oxford, ICML 2026) shows frontier models reliably escaping Docker containers through common misconfigurations — the same benchmark this repo maps to WASM in the Security section. Trail of Bits researchers (Judson & Hess, 2026) bypassed five agent-skill scanners and sandbox defenses in one study, and the DDIPE skill-poisoning attack (arXiv 2604.03081) measures 11.6–33.5% bypass rates against agent skill ecosystems. The pattern across all three: scanning and container defaults fail; the boundary that holds is the one enforced between the code and the host — the layer Cell ships (per-claim provenance: docs/security_posture.md).
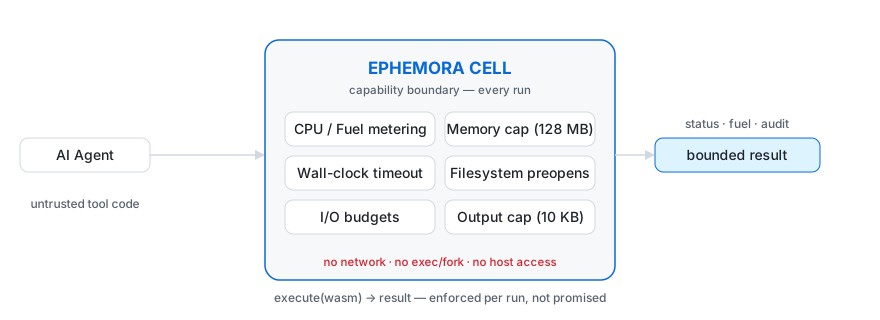
AI Agent ──▶ Tool / MCP ──▶ Ephemora-cell ──▶ WASM ──▶ bounded result
Every execution answers three questions at once — attached to the result as _meta.execution, canonicalized (RFC 8785 JCS) and signable:
"Verifying. Not claimed." is data, not a slogan: any record can be re-checked — rewrite one field and verify() fails. Runnable demo: python examples/signed_record_demo.py.
Security Model
Cell assumes that guest code is untrusted. The host explicitly decides what the guest can access — and the runtime enforces that decision per execution.
HOST
────────────────────────────
       Cell Boundary
────────────────────────────
GUEST / UNTRUSTED CODE
By default: no network · no arbitrary filesystem access · no process spawning · no unrestricted environment access — and bounded CPU/fuel, memory, execution time and output.
Security is never opt-in. Every execution — in-process or isolated — runs under enforced limits (CPU fuel, memory, wall-clock time, output caps — always on; the guest cannot reach them off and the caller sets their size, not their existence). Two deliberate exceptions exist and are named wherever they matter: max_wasm_bytes (how big a module a run may load) and allow_fsync (whether WASI sync calls are permitted) — both attested in the signed baseline, both off-by-default-widened-in-no-profile. The one thing you choose is the process boundary: add --isolated (or call run_isolated()) when the module comes from outside your own build — agent output, third-party plugins, PR-contributed code. The in-process path stays for modules you build and trust. The enforced defaults:
The same rule governs language features: every WebAssembly proposal Cell's shipped WASI surface does not need is enforced off in the engine config (threads, function-references, exceptions, GC, tail-calls, stack-switching — attested in every security_baseline, compile-probe-tested per release). That is a deliberate structural defense: the 2025/26 record — fuel accounting dropped across call_ref/try_table calls (GHSA-m63x-6p34-q65x), a Cranelift aarch64 heap escape (CVE-2026-34971), and the vm2 escape riding WebAssembly try_table exception handling (CVE-2026-26956, secondary sources) — repeats one pattern: sandboxes diverge exactly where a proposal quietly flipped to default-on. Cell keeps that surface at zero and pays the cost in what guests can't run, not in what the host can't guarantee. Full proposal table: SECURITY.md.
Additional controls: I/O budgets (io_cpu_seconds / io_budget_bytes — walls for host work, not just guest compute), dual-ABI (WASI Preview1 + WASI 0.2 components, opt-in), memory64 opt-in, GC-heap declared cap, named state (64 entries · 256 KiB · 1 MiB per session), and an egress sidecar mediator (docs/egress_patterns.md) — the guest has no sockets (enforced); with --egress-allow the MCP engine mediates a tool's request artifact after the run and reports the decision under _meta.egress. Off by default. The --egress-allow path enforces the allowlist only; a grant's expiry, usage cap and revocation are enforced when a GrantLedger is attached (ephemora_cell/grant_ledger.py, ADR-013); DNS-rebinding is closed at resolve time (hostnames whose answers fall in Cell's own special-use address registry — private, loopback, link-local, CGNAT, metadata, documentation, and the IPv4 embedded in mapped/6to4/NAT64 spellings — are refused; the decision is not delegated to ipaddress.is_private). A grant is authenticated before it is enforced: --egress-trust names an operator-maintained trust root outside the grants directory, and every grant file must be a DSSE envelope signed by a key that root names — unsigned, tampered, foreign-signed or expired refuses startup (ephemora_cell/grant_trust.py, ADR-013).
Quick Start
Three commands: install Cell, run something untrusted, read its audited receipt.
1 — Install (use a virtualenv; on Ubuntu ≥ 23.04 / Fedora a bare pip install
is refused by PEP 668. Windows: use Git Bash or WSL, and python instead of python3):
python3 -m venv .venv && source .venv/bin/activate
python -m pip install ephemora-cell
2 — Run something untrusted (the repo ships examples, or bring any .wasm):
git clone https://github.com/MichaelS1011/ephemora-cell.git && cd ephemora-cell
ephemora-cell run examples/hello.wasm --isolated
(adds OS-level process isolation around the run, a few ms — recommended for code you didn't build)
Hello from Ephemora Cell!
3 — Read the audited receipt — same run, machine-readable. Here a hostile module
(examples/fuel_bomb.wasm) is given a 100-unit fuel budget and stopped, exactly as
budgeted:
ephemora-cell run examples/fuel_bomb.wasm --fuel 100 --isolated --json
{
  "status": "fuel_exhausted",
  "exit_code": 0,
  "fuel_consumed": 100,
  "fuel_budget": 100,
  "stdout_bytes": 0
}
Same from Python — every result carries status, cost and captured output (see API & CLI):
Time to value: no policy file, no access rules, no container to provision — one pip install and you are running untrusted WASM under a hard fuel + memory boundary at ~0.5 ms warm (the same call took a stock docker run ~186 ms to start; measured macOS M5 n=100, benchmarks/results/2026-09-14/competitive_benchmark.json, DGX numbers in benchmarks/results/2026-09-20/).
Scale check: the one-liner path sustains ~3M executions/hour per core (n=500, hello.wasm, Mac M5 — regenerate with the snippet in docs/recipes.md); the pooled hot-loop path reaches ~5.5M/hour.
Where to next: agent/tool isolation → MCP Integration (3-line setup) · CI gating for untrusted PRs → AI Agent Integration · CLI reference and usage recipes → docs/recipes.md. Something failed? The usual suspects are venv not activated, python3 vs python on Windows, or a wrong .wasm path — docs/recipes.md covers them.
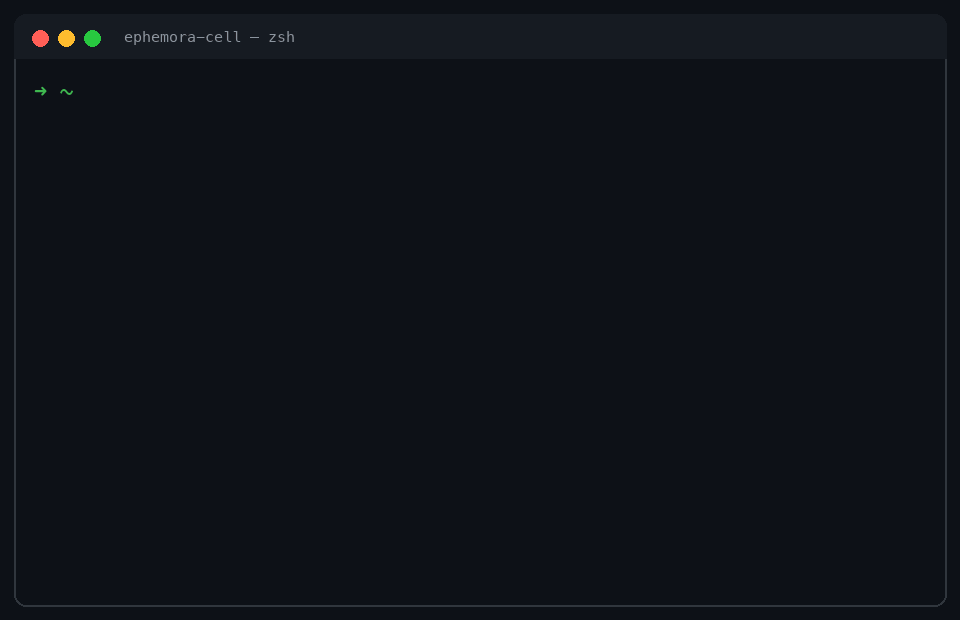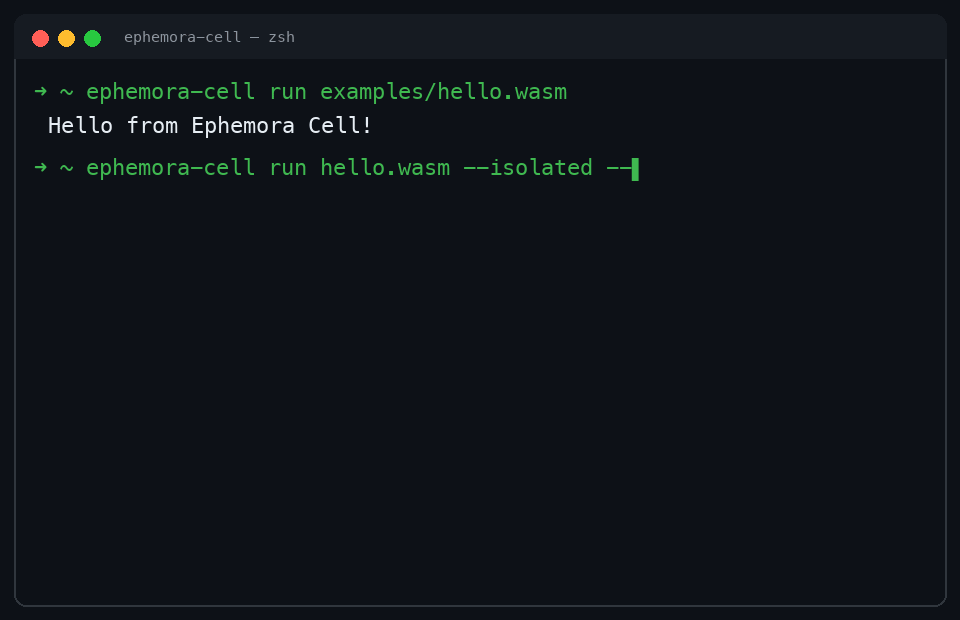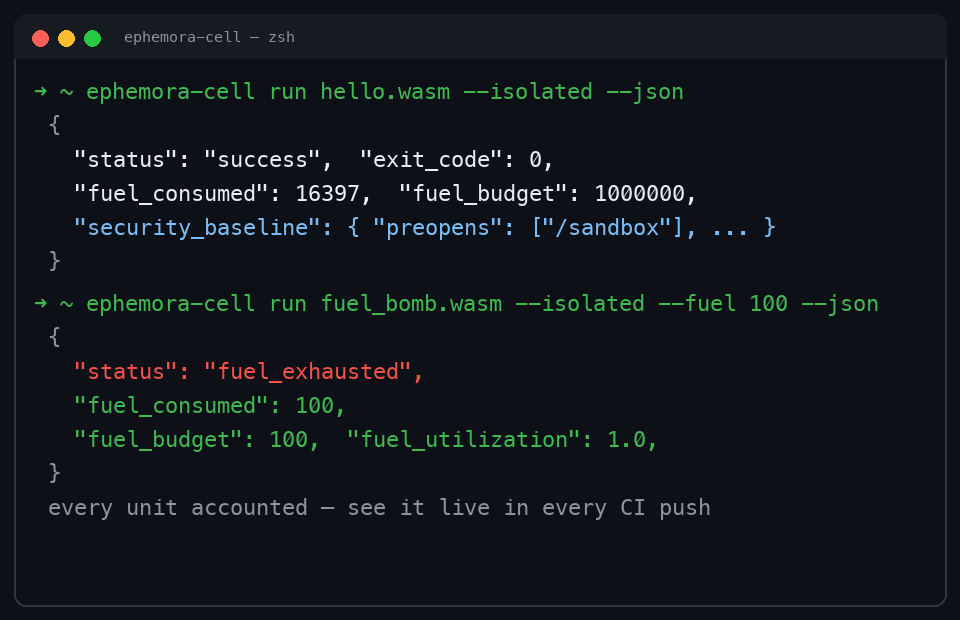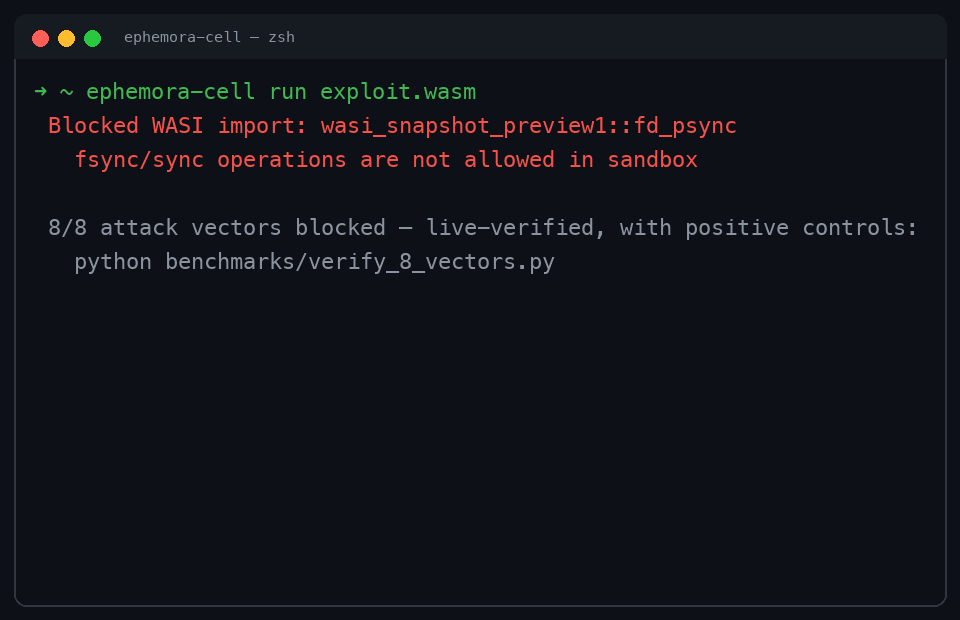
Real CLI session — every line is verbatim output of the command printed above it. Install is the 1.1.0 wheel from PyPI; the examples/ and benchmarks/ paths are a clone of the repo, and the last scene needs the optional tools-signing extra installed just before it. The arc is what one execution is today: fresh run → the boundary it got (fuel, memory limit, preopens, allow_fsync: false) → a runaway module stopped at exactly 100 of 100 units → capability and access denials measured against the live runtime, positive controls included → signed evidence that detects a single rewritten field. Wall-clock and throughput are deliberately not in the frames: they are platform-dependent, and a demo that shows them ages into a false claim.
The same commands are a development loop — edit, run, read the receipt — with no Dockerfile, no image build:
Failures come back graded, not crashing: an infinite loop returns status: "fuel_exhausted" with its receipt, a memory hog memory_exceeded, a crash a non-zero exit code — the same statuses the auto-grader and the CI test-bench job consume. A misbehaving tool never takes your terminal with it.
MCP Integration
Listed in the official MCP Registry (io.github.MichaelS1011/ephemora-cell-mcp, stdio via PyPI) and graded on Glama (tool definitions A, maintenance A, 3 tools — Glama's live classifier; see the hero badges above). The call flow is the hero diagram above: the agent's tool call enters the stdio server, the tool runs inside the Cell, and the result comes back with its execution record.
pip install ephemora-cell
ephemora-cell-mcp          # bundled tools: clock + echo; --tools-dir ./tools replaces the bundled set with your own

# One-line setup for GitHub Copilot in VS Code:
code --add-mcp '{"name":"Ephemora Cell","command":"ephemora-cell-mcp"}'
Ask your agent for the current time: the answer comes from the bundled clock tool — a WASM module reading only the WASI real-time clock — and the call report shows exactly what that answer cost.
Runs entirely on your machine — with any MCP client and any model, including local ones. The MCP server is a plain stdio process installed from PyPI: no API key, no cloud account, and tools execute offline inside the WASM sandbox (no network unless you explicitly allow it host-side). Point Claude Desktop, VS Code/Copilot, Codex, LM Studio or your local-model stack of choice at it — the sandbox side never leaves your hardware. How much the agent gets out of the tools then depends on your client and model's tool-calling ability; the sandbox itself adds no requirements beyond a local machine.
What you get:
Run untrusted, agent-built tools locally. Every tool is a WASM module inside a Cell sandbox — no network, fuel- and memory-bounded, output-capped. If a tool misbehaves, it hits a wall, not your machine.
Verify every call, not just the install. Each result carries its execution record (_meta.execution), and the native get-policy tool reports the exact sandbox policy per tool — computed from the same code path that enforces it, so report and enforcement cannot drift. The protocol does not verify _meta, so with --receipt-signing-key each receipt additionally carries a DSSE signature (_meta.attestation) over the same bytes — verifiable out-of-band by the caller with the operator's public key (execution_report.verify_execution_attestation). Inside the signed bytes each receipt carries a one-of-one block (report_id, issued_at, the tool it answers for), so a receipt is evidence about one execution rather than about a shape that many calls could produce — and max_age_seconds lets a caller refuse a stale one. Cell proves uniqueness; the verifier decides whether it has been seen before — deduping report_id across presentations stays the caller's job, because the evidence persists while the execution state does not. Policy reads are tools; policy writes are host decisions (ADR-006): an agent cannot grant itself network or filesystem access, and no socket connect succeeds (Preview1 exposes no socket APIs; in the WASI 0.2 world connect is denied at call time — measured).
Stateless by design (2026-07-28 revision). Clients on the current revision skip the initialize handshake entirely; results carry resultType: "complete" and tools/list answers with ttlMs/cacheScope. Handshake-era clients (Claude Desktop, VS Code, Codex, …) keep working unchanged — both eras served from one process and tested side-by-side against the official MCP SDK in CI. Handshake-era traffic is ordered as the legacy revisions require: a tools/list/tools/call that arrives before initialize is refused with -32600 before any WASM runs, and so is a repeated initialize; the exemption belongs to the stateless revision, not to the _meta key — declaring a handshake-era version there still requires the handshake. The point of that split is the deployment shape: an MCP server may be long-lived while every execution inside it is fresh. A connection, a process or a session is not a place where authority or execution state accumulates — each request carries its own version and capabilities, each tools/call starts a new sandbox, and nothing from a previous call is inherited by the next. Details: docs/mcp.md.
Isolation priced for every call — three distinct numbers (comparison):
The promise is four words, and each is a named gate. Ephemeral, stateless, capability-bound, verifiable — not marketing adjectives but the product's four invariants, pinned one test per word in tests/test_execution_invariants.py: after a run there is no execution environment left to reuse (cleanup() returns the residue it could not remove, so a surviving directory is a failed assertion, not a silent success); run B reads nothing run A left — measured across 1000 back-to-back runs with guest-written files, stdout, generated identifiers and host-side state, on the pooled path too (the default I/O budget forces a per-run engine, so a statelessness test that never lifts it is testing the wrong path); no operation carries authority that was not granted, and the run attests exactly which preopens it got; and the receipt verifies against the operator's key over the exact bytes shown to the caller, with a foreign key and an edited field both refused. The claim a reviewer should test us on: no execution state survives into the next execution — measured, not asserted: 1000 / 300 / 40 consecutive run-pairs on the engine-pool, in-process-per-run and isolated-subprocess paths, 0 leaks on each, plus 40 audits whose writer was SIGKILLed mid-append (benchmarks/statelessness_probe.py, dated result in benchmarks/results/2026-10-05/).
The host never follows a path the guest can write. WASI protects the guest from escaping a preopen, but the host also opens names inside the guest's own sandbox — the sidecar request/response artifacts, grant files, the audit books — and WASI accepts a path_symlink with a relative target (../../../../…), so a guest could plant a pointer that an ordinary host-side open() resolves outside the sandbox. Since 2026-10-05 every such read goes through O_NOFOLLOW plus a regular-file check on the descriptor it actually obtained, every publication is atomic (replace the name, never write through it), a refused artifact is an audited denial whose reason carries no absolute host path, and the request document is bounded at the read (1 MiB). Gates: tests/test_host_file_boundaries.py, SECURITY.md.
What a signature means here, in three answers. What is signed: not the JSON sitting next to it, but exactly canonical_bytes(record) — RFC 8785 JCS over the record's fields, wrapped in a DSSE v1 PAE, so a signer cannot sign one object and present another and verify_execution_attestation re-checks all three (payload type, payload bytes, signature) before it returns True. Who may sign: an operator-anchored key only — receipts with the deployment's signing key, grants against a trust root that lives outside the directory grants are read from, and neither accepts a key the artefact names for itself. What a valid signature means: that a trusted signer attests these exact bytes. It does not mean the execution was safe, it does not mean the sandbox enforced anything beyond what the record itself says, and it is not an authority unless the audience matches — a receipt signed by the operator key is not a grant, and a grant is not a receipt (pinned: the receipt verifier accepts only Cell's own receipt audiences). Cell proves uniqueness; the verifier decides whether it has been seen before, because the evidence persists while the execution state does not.
The agent cannot rewrite its own security boundary. The agent may only propose a capability; the host verifies signature, module hash and policy out-of-band before anything runs; the runtime enforces per execution and returns evidence. No arrow in that chain points backwards.
vs Microsoft Wassette. Wassette is Microsoft's capability-based runtime for MCP tools, built on the same Wasmtime engine family — its OCI pull model moves the trust decision to install time; Cell adds what a caller can verify per call. Full side-by-side (re-verified 2026-09-18): docs/comparison-mcp-servers.md.
This is an execution boundary, not a claim that guest software is trustworthy. Cell does not evaluate whether a module is malicious or correct — a guest can still misbehave within the budgets it was given.
AI Agent Integration
Untrusted PR code in GitHub Actions. This repository ships a composite action: run a WASM module in the Cell sandbox inside your own workflow — with fuel metering, memory cap, epoch timeout and (default) the --isolated subprocess path (OS-level rlimits, hard kill):
- id: run-tool
  uses: MichaelS1011/ephemora-cell/action@main
  with:
    module: path/to/module.wasm   # e.g. built from a PR-provided recipe
    profile: llm
    # fuel: 500_000
- run: echo "status=${{ steps.run-tool.outputs.status }} fuel=${{ steps.run-tool.outputs.fuel_consumed }}"
Non-success statuses fail the step (fail-on: non-success, default) — a module that burns its budget or trips the memory cap cannot take your workflow with it. This repo dogfoods the action on every push: .github/workflows/action-demo.yml runs a benign module and feeds the same module a 100-unit fuel budget, asserting live that the sandbox stops it and accounts every unit.
CI runs two framework-adjacent integration suites against real SDKs — integration/test_hermes_subagent.py and integration/test_nemoclaw_isolation.py. The other scripts in integration/ (LangGraph, CrewAI, AutoGen, OpenAI Agents SDK, Semantic Kernel) are examples that need their own SDK install and are not CI-gated; nothing in this README claims otherwise.
Use Cases
What you can build with Cell:
AI Code Execution — safely execute code generated by an LLM, with explicit limits:
result = run_wasm(
    "llm_generated.wasm",
    max_fuel=200_000,
    timeout_seconds=5,
    allow_dirs=("/input", "/output")
)
MCP Tool Sandbox — run MCP tools inside a bounded execution environment (see MCP Integration).
Plugin Runtime — accept user-uploaded plugins without giving them host-level access (WASIConfig(allow_dirs=("/data",), max_fuel=500_000) — same shape as the snippets above).
Agent Tool Runtime — give autonomous agents controlled access to computational tools.
Verifiable Execution — produce structured and optionally signed records describing an execution (Execution Records).
Also documented: serverless/edge workloads, air-gapped validation, WASI 0.2 components, FastAPI integration — docs/recipes.md.
Architecture
Cell executes the .wasm — it does not know the source language. One command compiles five languages, and the runtime sits underneath your stack:
The enforcement stack — module → engine → capability surface → budgets → record — is diagrammed in docs/security_posture.md. The primary API is deliberately simple — run_wasm(wasm) → result, with status, exit_code, stdout, stderr, elapsed_ms and fuel_consumed on every result (full surface in API & CLI). That makes execution suitable for auditing, policy enforcement, and resource accounting — not just running code. Full CLI (run, --json with security_baseline, inspect, benchmark, build) in the CLI docs and ephemora-cell --help.
Any language that compiles to WASM. One-command build with actionable error hints:
ephemora-cell build src/main.rs # inside a cargo project → tool.wasm → run it
What does not run: native Python, Node.js/npm packages, or Linux/ELF binaries — Cell executes WASM modules and WASI 0.2 components, nothing else. Scripting languages run only as interpreter binaries you compile to WASM (or componentize, e.g. componentize-py, jco/StarlingMonkey) and bring yourself — Cell ships no interpreters, and GC/threads-based ports (Kotlin, Dart, …) stay locked until the GC-heap gate in SECURITY.md opens. Support matrix and recipes: docs/languages.md, docs/recipes.md.
All five compiled-language gates verify on every push (.github/workflows/ci.yml). Platforms: macOS (Apple M5) ✅ · Ubuntu 24.04 ✅ · DGX Spark GB10 ✅
Execution Records
Around the sandbox sits a verifiable trust chain for third-party tools:
TOOL ──▶ SIGNED MANIFEST ──▶ HOST VERIFY ──▶ EPHEMORA CELL ──▶ SIGNED EXECUTION
        (vendor ships)     (fail-closed,      runs inside       RECORD
                           hash + policy      the sandbox       (tamper-evident)
                           check)
Anything failing verification is rejected before a single instruction executes — execution never depends on a happy path.
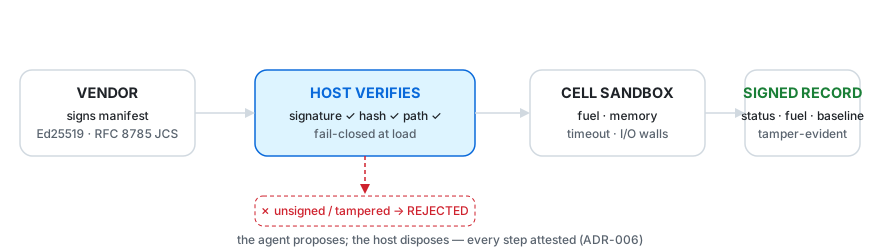
- Signed tool manifests. Third-party tools ship an Ed25519-signed manifest (RFC 8785 JCS); the server verifies signature and module hash before registering and rejects unsigned, tampered or hash-mismatched tools fail-closed — a bare
.wasm without a manifest never loads in signed-tools mode. ephemora-cell-mcp --require-signed-tools pub.pem, sign with python -m ephemora_cell_mcp.sign_tool.
- Governed dynamic loading. An agent can only propose a tool — a
tool.request.json dropped into an operator-allowlisted directory; the server evaluates it before each incoming message, verifies signature, module hash and policy, then installs and announces it (notifications/tools/list_changed). The agent proposes; the host disposes (ADR-006).
- Signed execution records. Any run folds into a tamper-evident record covering status, fuel, timing and the attested security baseline — rewrite one field and verification fails. Runnable demo:
python examples/signed_record_demo.py.
- Pre-exec / receipt split (ADR-008).
PreExecutionRecord signs what a run will do (module digest, policy fingerprint, input digest) before it runs; the receipt's optional back_link binds it to exactly that attestation. Open-standard envelopes (DSSE v1, detached JWS) carry the same JCS bytes for ecosystem interop — no network client, no dependency.
- Trusted fast path.
ephemora-cell-mcp --pooled serves verified tools from the pooled engine at ~0.5 ms per call instead of ~12 ms (measured) — the relaxed I/O wall is attested in get-policy.
- Host-mediated egress.
ephemora-cell-mcp --egress-allow https://api.example.com/v1 gives the guest's sidecar.request.json a real caller: the engine mediates it after the run against that allowlist and reports the decision under _meta.egress. Off by default; the no-socket boundary is the enforced guarantee. The --egress-allow path applies the allowlist only; --egress-grants-dir DIR --grant-ledger PATH loads each tool's signed grant and enforces its expiry/usage cap/revocation in one critical section (ephemora_cell/grant_ledger.py, load_egress_grants, ADR-013); DNS-rebinding is closed at resolve time (resolutions refused against Cell's own special-use address registry, not against ipaddress.is_private). A grants dir requires --egress-trust FILE: a trust root of operator-held Ed25519 keys, kept OUTSIDE the grants directory, because a key delivered with the artefact proves nothing about the artefact — each *.egress.grant.json must be a DSSE v1 envelope over the grant's canonical bytes, signed by a trusted, non-retired key inside its own window, for the grant audience, and any failure refuses startup for the whole directory (ADR-013). Two scopes complete that picture, both disclosed by get-policy: a grant NARROWS --egress-allow instead of replacing it — for the URL the guest wrote, for every redirect hop, and for the resource envelope, since a grant carries endpoints and methods only (an endpoint outside the operator's allowlist is denied before the ledger charges and spends no slot — grant_scope), and a tool with no grant file falls back to the allowlist alone unless --egress-grants-required denies it instead (ungranted_tools).
- A chain across runs (shipped in 1.1.0). Each run's pre-exec record and receipt are sealed into a signed
LedgerEntry JSONL chain (sequence + prev_hash), so a folder of evidence can be shown to be continuous, ordered and untampered — linkage verifies without any key, authorship only with one. Default-off and host-side; what it cannot see is a chain truncated at its end, which is stated in ADR-011 and tested. Check one: ephemora-cell ledger <path>.
- Budgets that survive the next call (shipped in 1.1.0). A tenant is a billing identity, not an isolation boundary:
--tenant ID --tenant-book PATH --tenant-max-runs N (or WASISandbox.run(tenant=…, tenant_budget=…)) reserves the run's own ceiling before it starts, books what it actually consumed, and refuses the next run over the cap — with a receipt that names the account. Overshoot is bounded by concurrent runs times the per-run walls; there is no mid-run kill here (ADR-012).
The two execution paths differ materially. run_wasm() runs the guest inside your process; run_isolated() adds OS-level walls around a disposable worker (and returns the report fields as a dict). For guests from outside your own build — agent output, third-party plugins, PR-contributed code — use the isolated path:
Rows marked ❌ in-process are documented-trusted: the knob is honored as a declared capability, not an enforced wall — a kernel-level cap there would limit your own process. Full matrix and rationale: SECURITY.md.
Security
Evidence ladder — strongest first. Every row is measured, the raw evidence is committed, and each run is reproducible:
Row 2 in context. The 18 scenarios are external (UK AI Security Institute, MIT — provenance note below). This mapping is the source-available execution-boundary slice of a broader benchmark and assurance program; the wider program — including the agentic escape evaluation the upstream benchmark actually runs — is part of the Ephemora enterprise edition (docs/enterprise.md).
Where the 18 scenarios come from. Not ours: the UK AI Security Institute's SandboxEscapeBench (arXiv 2603.02277, scenarios: UKGovernmentBEIS/sandbox_escape_bench, MIT) documents 18 ways code escapes container/Kubernetes sandboxes. This suite does something narrower: each scenario is mapped to its closest WASM/WASI equivalent and executed against Cell, no model in the loop. The primitives those escapes rely on (privileged modes, namespaces, cgroups, raw sockets) do not exist on the WASI surface; the scenarios with a WASM-expressible equivalent (filesystem, sockets) are denied by the live boundary. Prompt-injection and agent-behavior security are different layers — out of scope for an execution sandbox by design; the enterprise edition runs the wider assurance program (docs/enterprise.md).
What we do not compare — and why. Prompt-injection suites (garak, InjecAgent) test the model and agent layer, not the execution boundary — out of scope for an execution sandbox. Cloud sandbox providers are cited from third-party sources with their source status; third-party numbers never appear in the same table as our measured cells. Startup and throughput benchmarks live in docs/performance.md with their scope caveats.
The guest receives only the capabilities explicitly made available to it. Live verification of eight attack classes (benchmarks/verify_8_vectors.py) — measured against three boundaries, same intents, same measurement rule (exit code decides, nothing hardcoded):
The boundary is three layers, and the table measures them separately:
- Layer 1 — WASI surface: the guest format itself has no shell/fork/socket entry points to call.
- Layer 2 — Sandbox policy (always on): preopen default-deny, dangerous-directory filter, sync-call traps,
wasm_threads=False, allow_env — enforced per execution. Two values are operator-configurable by design: max_wasm_bytes (how big a module a run may load) and allow_fsync (a caller's durability choice). Neither is reachable by the guest, and both are attested in the signed baseline, so an opened run never reads like a closed one.
- Layer 3 — OS process wall (
--isolated): a disposable worker process with OS rlimits and a hard kill — the mitigation layer for engine 0-days (SECURITY.md documents the April 2026 wasmtime advisories).
Result: 8/8 attack vectors blocked (live-verified, default configuration, WASI Preview1 path); both Docker baselines are measured live per run — never hardcoded. The WASI 0.2 component path is a separate boundary and does not carry the sync blockade today — measured, not asserted: python benchmarks/component_sync_probe.py shows both wasi:filesystem/types sync calls completing into the host when a directory is granted, while the default component run gets no preopen, so the surface needs an operator grant first (SECURITY.md).
For context, the same eight intents were measured against gVisor (runsc, pinned release, executed in CI twice for determinism): 8/8 ALLOWED. gVisor walls the host off from the container, but the guest keeps the Linux ABI — so the same primitives stay available to guest code. Expectation matrix pre-declared in benchmarks/gvisor_docker_probe.py; raw evidence: benchmarks/results/2026-09-19/08_gvisor_docker_attack_probe.json (committed from the gvisor-boundary CI job).
¹ Hardened = exactly these flags — tell us which to add: --network none --read-only --cap-drop=ALL --security-opt no-new-privileges --pids-limit 64 --user 65534:65534 (image pinned by digest; Docker's default seccomp profile is active in both columns). Both hardened blocks are --read-only file-system effects — the flags wall the container off, not the guest in: socket creation, the container's own /etc/passwd, fork, threading and environment stay available to the guest.
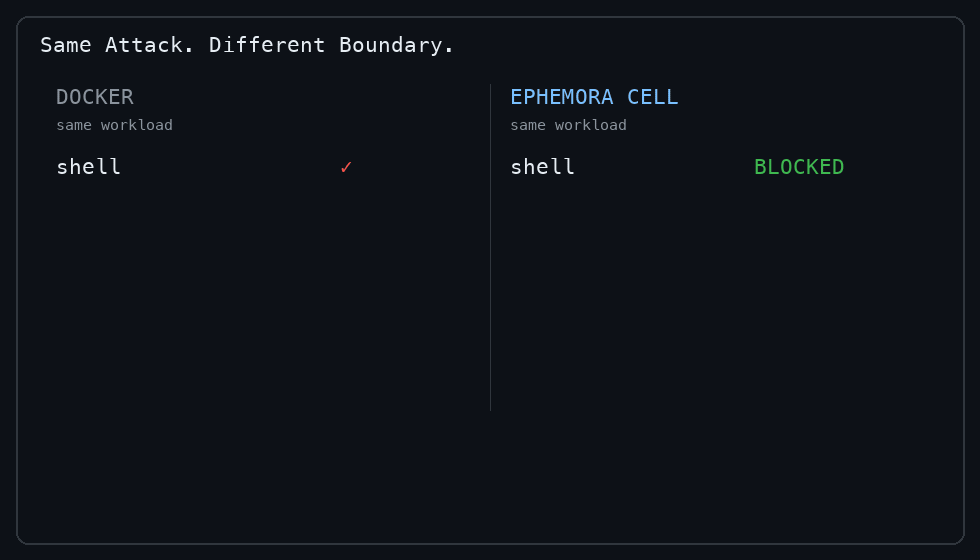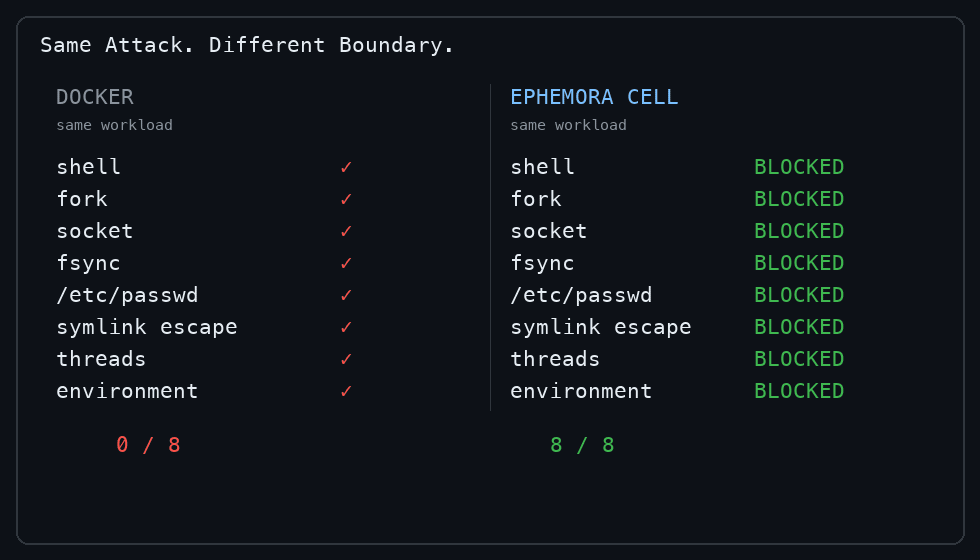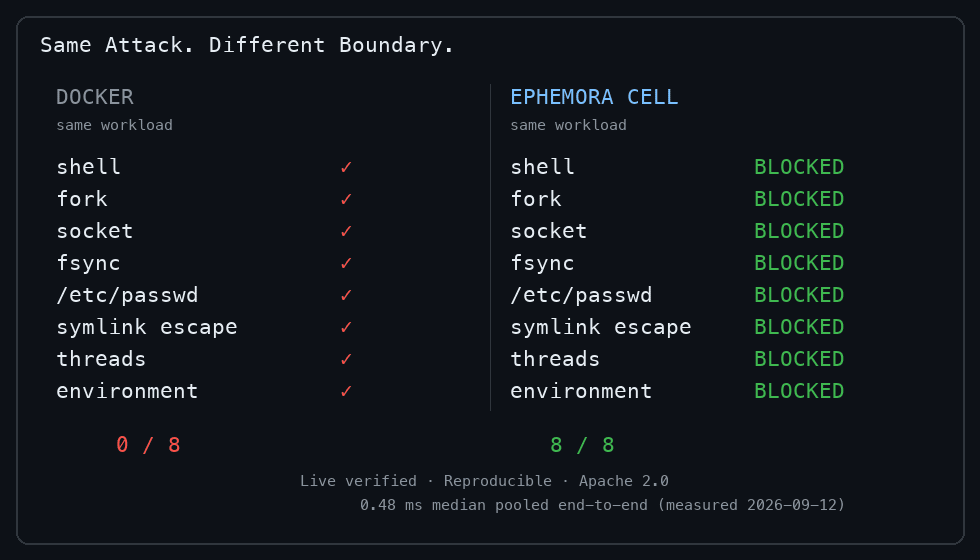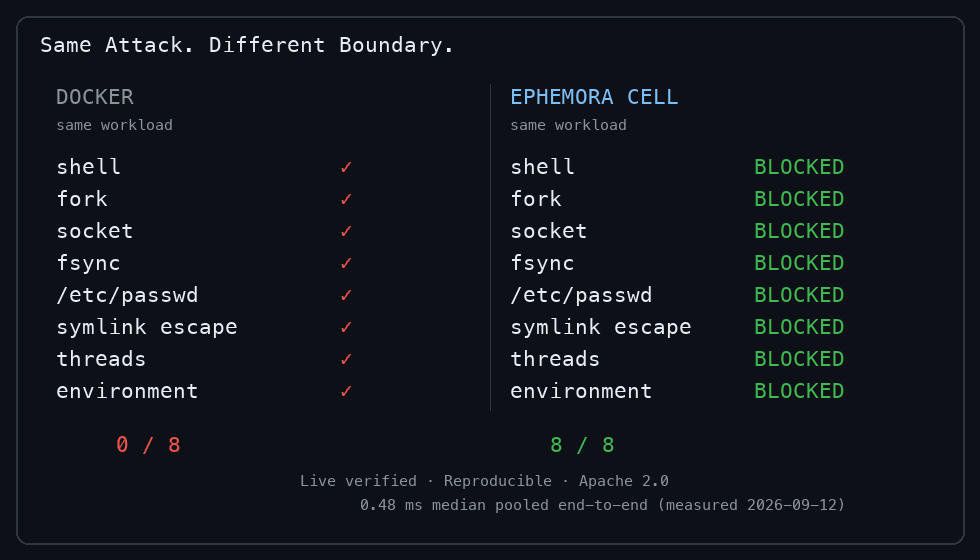
Same eight attack primitives, measured live: stock python:3.12-slim 0/8 blocked, hardened container 2/8 (both blocks are --read-only flag effects), Cell 8/8. Measured on two platforms with identical results — macOS arm64 (2026-09-18) and DGX Spark GB10 (2026-09-20, benchmarks/results/2026-09-20/*-dgx-aarch64.json). Reproduce:
python assets/demo_attack_probe.py          # stock Docker    ->  0/8 blocked
python benchmarks/hardened_docker_probe.py  # hardened Docker ->  2/8 blocked
python benchmarks/verify_8_vectors.py       # Ephemora-cell   ->  8/8 blocked
How the 8/8 is measured — environment, probe-by-probe equivalence between the Docker probe body and the Cell WASM guest, raw-evidence file list and the positive-control rule: docs/security_posture.md. In short: measured exit code decides, nothing hardcoded; every blocked vector pairs with a granted-capability control that must succeed.
- Raw evidence:
benchmarks/results/2026-09-18/ (01_hardened_docker_attack_probe.json · 02_docker_attack_probe.json · 03_cell_8_vector_verify.json) + historical benchmarks/results/2026-09-02/
MCP CVE replays. The official MCP reference servers have real, patched CVEs against this exact surface. benchmarks/mcp_cve_replay.py replays them as their original exploit paths — pinned vulnerable reference server vs. Cell, same files, positive controls on both sides (2026-09-17, measured:true):
- CVE-2025-53109/53110 ("EscapeRoute", symlink escape + prefix traversal): the vulnerable reference server leaked the protected file in both intents; Cell blocked both at the engine level (
EPERM/ENOTCAPABLE) — with the granted-capability control reading successfully on both sides.
- CVE-2025-54136 class ("MCPoison", payload swap after trust): a signed tool is accepted once, then a single tampered wasm byte makes the next governed-load request fail closed (hash mismatch).
- Same replays against WASI 0.2 components (evidence,
abi: "component"): the component path denies the same escape intents (symlink escape → EPERM, traversal → no preopen base) and the same governed-load tamper fails closed. The network vector gets its own intent — the WASI 0.2 world links wasi:sockets (unlike Preview1), so a TCP connect is attempted under the sandbox and refused at call time, with the granted-read control passing in the same run.
Not self-written test suites — the shipped CLI and the engine configuration Cell ships are run against both official suites: the WebAssembly/wasi-testsuite preview-1 suite through a runtime adapter, and the official WebAssembly core spec suite (W3C Wasm 3.0 era, wast2json harness) — evidence committed under conformance/results/:
- WASI: 72 pass, 1 documented by-design xfail, 0 fail across the applicable preview-1 suites (pinned suite commit
609c44613995, 2026-09-14; 55 preview-3 tests skipped — Cell declares preview 1 only)
- Core spec (run 2026-09-19, pinned
b464a4cd100d, 257 files / ~36k commands): 31,931 pass with every deviation documented, none unexpected — 3,282 classified (memory64/multi-memory modules are by design outside the shipped engine config; v128 cannot pass through the wasmtime-py 47 binding; relaxed-simd files abort natively upstream), 684 text-format asserts skipped (wabt parser domain), and 46 asserts the artifact counts as fail, all at the wasmtime-py binding NaN-bit level, listed verbatim in the evidence JSON. Reproduce: python conformance/run_core_spec.py
- A weekly CI job re-runs the pinned suite and uploads the raw JSON, so drift surfaces within a week (
.github/workflows/wasi-conformance.yml). Known, documented runner quirk: shared ubuntu x86_64 runners show rare wasmtime engine aborts on varying fs tests; the CI job absorbs each abort with a single recorded retry (adapters/cell_retry_wrapper.py, every retry visible in the evidence JSON) — a healthy run lands 72 pass, as in the 2026-09-19 CI run — deterministic on macOS arm64 and in clean containers (conformance/README.md)
- The one deviation is documented:
sock_shutdown-invalid_fd expects EBADF on a runtime with no preopens; Cell's sandbox scratch dir is preopened as fd 3 by design, so the call returns ENOTSOCK. The property Cell claims — no socket surface — is unaffected.
- Honest scope: this is standards conformance, not a security certification. No third party certifies Cell; the evidence is the pinned suite, the committed JSON and the CI history.
Can you break Cell? Found an execution path that violates the documented security boundary — an escape, a budget bypass, an attestation gap? That is exactly the report we want: SECURITY.md (private disclosure, responsible handling). The threat model and its documented residual risks tell you where to aim; the methodology boxes on this page tell you how we measure. Security research on Cell is welcome.
What does the security boundary cost? 0.376 ms — the warm wall-clock overhead a sandboxed run adds over the same work run bare (measured, not estimated).
Latest reproducible benchmark — 2026-09-14 · Mac M5 · wasmtime 47.0.1 · n=1000. Every number below regenerates from a fresh clone via the commands at the end.
Cold vs. warm (2026-09-14, n=300 each, fresh sandbox per run vs. cached engine, first run discarded): cold median 0.59 ms guest / 0.99 ms wall, warm median 0.55 ms guest / 0.93 ms wall — sandbox overhead (warm wall − guest) = 0.376 ms (overhead_warm_ms, benchmarks/results/2026-09-14/pov_benchmark.json).
Live cold-start comparison (2026-09-14, same Mac, n=100 per image after warmup): docker run python:3.12-slim 185.9 ms vs Cell 0.49 ms = 383× — this is a container-cold-start vs invoked-WASM comparison for this benchmark workload, not a general claim that WASM is always faster than Docker.
Reproduce: python benchmarks/pool_vs_budget.py · python benchmarks/competitive_benchmark.py (raw results with measured:true committed under benchmarks/results/). Agentic workloads and more: docs/performance.md.
Sandbox tax on an industry-standard workload (EEMBC CoreMark 1.01)
The same committed coremark.wasm (EEMBC CoreMark 1.01, pinned sources, wasi-sdk-34) runs interleaved under three Cell configurations and, when their CLIs are on PATH, under external engines — every run must pass CoreMark's own self-validation. Scores are CoreMark's self-timed "Iterations/Sec":
Read as facts, not a ranking: on this workload the engine choice spans a ~9–12× range depending on platform, the Cell sandbox layer costs 8.6–10.0% over the bare engine on the same machine, and instruction-level fuel metering a further 12.5–14.7%. External engines are context, not competitors measured by Cell's API; wasmer requires --enable-tail-call (the build ships the upstream Lime1+tail-call feature set). Evidence with verbatim commands, versions and per-run scores: benchmarks/results/2026-09-19/09_coremark_wasi_*.json. Reproduce: python benchmarks/coremark_wasi.py --rounds 3.
Fuel counts are deterministic per platform (fuel_spread: 0 on every host measured) but platform-bound — never compare across hosts (details and measured cross-platform examples: docs/performance.md, python benchmarks/determinism_probe.py).
Engine backend & execution mode
Every number on this page is a Cranelift number: the Python binding cannot select an interpreted backend (Pulley/Winch unreachable, asserted in tests/test_surface_audit.py), so no fallback can silently change the posture. Details: docs/performance.md.
API & CLI
Python API — the primary surface is deliberately simple:
from ephemora_cell import run_wasm, run_isolated, WASIConfig, WASISandbox

result = run_wasm("tool.wasm", max_fuel=1_000_000, timeout_seconds=30)
result.status        # SUCCESS | ERROR | TIMEOUT | FUEL_EXHAUSTED | MEMORY_EXCEEDED
result.exit_code
result.stdout        # 10 KB cap
result.elapsed_ms
result.fuel_consumed

# OS-level process wall for untrusted guests:
result = run_isolated("tool.wasm", config=WASIConfig(max_fuel=500_000))
Profiles (plugin, llm, edge, default, analytical, interpreter), named state, disk quotas and GC-heap caps are WASIConfig knobs; the component path is selected per call via run_wasm(..., abi="component") — docs/recipes.md has the recipes (FastAPI, serverless, air-gapped, WASI 0.2).
interpreter is the budget preset for running a bring-your-own interpreter
as the guest (CPython-WASI and friends): a larger module cap, more memory,
more fuel, a longer clock, and the host-CPU wall an isolated worker needs to
compile a 22 MB guest first. It ships no interpreter, opens no sync exception
and grants no filesystem or environment access — the language posture stays
ADR-009, and
docs/languages.md carries the measured numbers.
CLI — five verbs cover the loop:
ephemora-cell run       Execute a WASM module (--json, --isolated, --fuel, --stdin, --profile, --abi, --tenant)
ephemora-cell inspect   Imports, exports, memory — what a module wants, before you run it
ephemora-cell benchmark Cold/warm latency and fuel spread
ephemora-cell build     Compile Rust/Go/C/AssemblyScript/Zig straight to WASM
ephemora-cell ledger    Verify a run chain: linkage and order, and what it cannot prove
ephemora-cell --help and docs/recipes.md for the full reference.
Limitations
Cell is: the minimal execution boundary for untrusted code — a WASM/WASI sandbox with explicit capabilities and budgets, a resource-accounted runtime, an embeddable Python library, a CLI, an MCP execution layer.
Cell is not: a persistent workspace · a VM · a container orchestrator or a general container replacement · a malware detector · a multi-tenant cloud platform · an agent framework · an LLM · a code generator. It holds no state you are meant to come back to: name-value state is a bounded, per-session convenience (max_state_entries · bytes per value · per-session budget), not storage, and authority never survives a run.
Use Cell when: code is untrusted or dynamically generated · tools come from third parties · an AI agent executes arbitrary programs · you need explicit resource budgets · you need structured execution metadata. Do not use Cell for long-running I/O-heavy services — that is what the --isolated subprocess wall or a microVM is for (see docs/performance.md for the measured third-party comparison).
What each enforced control does not claim — every row is an honest boundary, tested at the boundary:
The goal is narrow: make untrusted execution cheap enough and controlled enough that an application can safely do it by default.
Full details: SECURITY.md (policy, known limitations) · docs/threat-model.md (adversary model, trust boundaries, resource-exhaustion matrix) · docs/security_posture.md (arXiv 2509.11242 evaluation, fuel boundary, related research).
Roadmap
Real, gated items — no dates promised:
- Engine upgrade gate (in progress): wasmtime 48.0.3/49.0.1 closes the 2026 fuel-amplification advisory (GHSA-m63x-6p34-q65x) and the WASIp3-streams advisory, and the 2026-10-02 wave (uncharged
poll_oneoff host work, fd_readdir padding leak) is only closed one step higher at 48.0.4/49.0.2 — that pair is what the gate watches for (SECURITY.md, scripts/watch_upstream.py); blocked on Python wheels publishing to PyPI (scripts/check_wasmtime_patch.py watches), then fuel determinism re-qualification and a re-run of the FS-escape matrix, which has been a strict gate since 2026-10-04 — the five companion vectors are plain asserts, measured denied on the pinned engine on both CI legs (macOS arm64, linux/amd64), so an engine bump that re-opened one of them would fail CI rather than xfail it (tests/test_fs_escape_matrix.py).
- WASI 0.3 evaluation gate: WASI 0.3 (Component-Model async) is deliberately gated off until the 0.3 surface ships in the Python wheels, the streams advisory line is closed, and the surface has its own budget qualification (docs/recipes.md).
- Threading opt-in phase: shared-everything threads stay frozen by default; enabling them is a separately security-reviewed opt-in with thread-aware fuel and wall-clock accounting (SECURITY.md).
Testing & Verification
Release gate, measured on a fresh clone of the release commit — not a per-host constant: 957 tests passing (4 skipped) · 89.98% statement coverage, shown as 90% (Cell + MCP, gate 80%) · 8/8 attack vectors blocked (default posture, WASI Preview1 path) · 72-pass official wasi-testsuite conformance (pinned, 0 fail) · CI-enforced on every push (tests, coverage, pip-audit, SBOM, bandit, official MCP SDK interop) — plus, on that same clone: pip-audit clean against the pinned wasmtime==47.0.1, the statelessness probe at 0 leaks, a wheel-only smoke against the installed artifact (its result is recorded in the v1.1.0 GitHub release), and an sdist clean-room container run. Pass counts move with the host's toolchain mix and its load (see the skip breakdown below and the review record); the artifact-level claims do not — see .github/workflows/ci.yml.
What "the suite" means here — one canonical number. 957/4 (961 collected) is what pytest reports on the environment CI uses on both legs: requirements.txt (the pinned wasmtime), the test deps, and the optional tools-signing extra (cryptography>=42) that every Ed25519 path needs. The 4 skips are toolchain gates in tests/test_builder.py: three are build-and-run gates that skip when their toolchain is absent (WASI_SDK_PATH, asc, go), and the fourth is inverted — the .zig guidance test skips when zig IS installed, because then the build is real and the guidance path is unreachable. On this host (zig present) that is 957 passed / 4 skipped; on a zig-free host the same commit reports the same 957 passed / 4 skipped and the same 961 collected — a different test carries the fourth skip (.zig build-and-run instead of .zig guidance), which is why the totals are invariant. A minimal install in a checkout — the same suite without cryptography — measures 850 passed / 66 skipped / 81% coverage (916 collected): 62 skips are Ed25519 paths that importorskip("cryptography") (signed tool manifests, governed loading, signed receipts, grant authentication), and 61 of them are individual tests plus one module-level skip of tests/test_grant_trust.py, whose 46 tests leave the collection and are replaced by that one skip entry (961 − 46 + 1 = 916) — plus the same 4 toolchain gates. Neither number is the suite weakening: signing paths are unverified-by-absence, not passing. Unpacking the sdist and running it there skips additionally the nine repository-inspection modules by design: across the last four commits of the 1.1 line a clean python:3.12-slim container (linux/amd64, root) measured 773–778 passed / 138 skipped / 0 errors, 0 failures on a quiet host — and up to two failures when the host ran other work at the same time, because the io_cpu_seconds watchdog charges worker startup CPU to the guest; each such test passes standalone and natively. The figure is quoted as a range with its conditions deliberately: pinning it to one commit would make the sentence false the moment the commit changes, which is recorded as an open accounting question in docs/security_review_2026-10-05.md rather than smoothed over — see docs/security_review_2026-10-05.md, so three figures describe three installation states and none of them is the suite weakening. The count is machine-checked against pytest --collect-only by scripts/check_test_count.py, so the release-count sentences cannot drift from the code; the prose figures around them (coverage %, minimal-install and container counts) are re-measured by hand at each release, not by the guard.
Documentation
Security review 2026-10-05 · docs/security_review_2026-10-05.md — what the six red-team lanes found, what was closed with a biting test, the three posture decisions the operator made afterwards (grant scope, ungranted tools, handshake order), the second pass that audited that same day's code and the seven findings it closed, and the ten items left open with the reason
Getting started · Quick Start above · docs/recipes.md — usage patterns (FastAPI, serverless, air-gapped, WASI 0.2) · integration/ — agent-framework examples
Security & evidence · SECURITY.md — policy, execution-path matrix, vulnerability reporting · docs/threat-model.md — trust boundaries, adversary model, resource-exhaustion matrix · docs/security_posture.md — attack-surface verification · conformance/README.md — official wasi-testsuite harness
Execution records & decisions · ADR-006 — who may change a running workload's security boundary · ADR-001…008 — all decision records · examples/signed_record_demo.py — sign and tamper-check a run
Performance · docs/performance.md — benchmarks · benchmarks/results/ — raw measured:true JSON
Integrations · docs/mcp.md — MCP server · docs/comparison-mcp-servers.md — CVE-to-probe mapping · action/ — composite GitHub Action
Languages · docs/languages.md — compile matrix · docs/egress_patterns.md — sanctioned API-call patterns · docs/observations.md — the two watch items we are deliberately not acting on, each with its exit condition
Enterprise · docs/enterprise.md — isolation vs. operation: when that conversation is worth having
Changes · CHANGELOG.md
About Ephemora
Ephemora-cell is the source-available isolation layer (BUSL 1.1, standalone — no Ephemora dependency). The Ephemora enterprise edition builds on Cell's isolation for production and regulated deployments. Cell is complete for isolation; the enterprise edition is complete for operation — see docs/enterprise.md for when that conversation is worth having.
License
Ephemora-cell is licensed under the Business Source License 1.1 (BUSL-1.1) — source-available, not open source.
- Free for non-production use — evaluation, development, research, testing.
- Business/production use requires a license from Ephemora — see docs/enterprise.md.
- Automatic conversion: each version converts to Apache 2.0 four years after its first public release.
- Versions ≤ 1.0.4.3 remain Apache-2.0 permanently — the change applies from the next release onward.
mcp-name: io.github.MichaelS1011/ephemora-cell-mcp
One agent action. One bounded execution. One controlled result.
Created by Michael Soppa.




